Last updated: October 13, 2026
Quick answer: automate XML sitemap validation after site changes with three checks—XML structure, URL status, and indexability—and in many teams the setup takes about 15–30 minutes to configure, then seconds to a few minutes per run depending on URL count.
In short, How to automate XML sitemap validation after site changes is to put those checks in the deployment path so a bad release fails fast before search engines waste time on broken URLs. If you publish through a CMS, webhooks, or CI/CD, this process turns sitemap checks into a repeatable quality gate instead of a manual SEO task.
Key Takeaways
- Validate that the sitemap lists only intended indexable URLs and that each one is canonical and crawlable.
- If GitHub Actions, GitLab CI, Jenkins, or similar ship your site, validate the sitemap in that same deployment pipeline.
- Use an event trigger plus a lightweight validator for CMS, webhook, or scheduled publishing workflows.
- Focus on live URLs, canonical URLs, crawlable URLs, and clean XML.
If your site changes often, the real problem is not generating a sitemap. It is catching the pages that disappear, redirect, noindex, or slip into the wrong domain after a release. I would treat XML sitemap validation as a post-change quality gate, not a one-off SEO task, and if your setup is complex you should confirm the rules with a technical SEO professional and the Sitemaps protocol. That approach suits sites with frequent content updates, CMS publishing, or releases that rewrite URLs. It is less useful if your site changes once a quarter and you can review the file manually in under 10 minutes.
What actually needs to be validated after a site change?
You need to validate that the sitemap still lists only URLs you want indexed, and that every listed URL still behaves like a canonical, crawlable page. If one of those pieces breaks, the sitemap becomes noise instead of a signal.
The first check is structural. The XML has to be well-formed, use the correct namespace, and stay under the standard sitemap limits: 50,000 URLs per file and 50 MB uncompressed, as documented by Google Search Central and the Sitemaps protocol. If you split sitemaps into index files, the index has to point to live child files, not stale paths.
The second check is URL health. Each URL in the sitemap should return a 200 status, or at least be intentionally handled in a way your site policy allows. A 3xx redirect in a sitemap is usually a smell, because the sitemap should point to the final canonical URL. A 4xx or 5xx is a hard fail.
The third check is indexability. A page can return 200 and still be the wrong target if it carries noindex, is blocked by robots.txt, or canonicalizes somewhere else. That is the part generic advice often misses.

| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Small site, changes a few times a month | Scheduled crawl plus XML parse check | Manual review misses redirects and canonical drift |
| Large ecommerce site, daily releases | CI/CD validation on deploy | Waiting for Search Console reports is too slow |
| CMS with many editors | Event-driven check after publish | A nightly job finds problems after bad URLs have been live for hours |
| Multi-language or multi-domain site | Per-sitemap validation by locale/domain | One bulk check hides cross-domain mistakes |
Quick check: if your sitemap can change without a developer noticing, you need automated validation, not a monthly spot check.
If you’re on a CI/CD pipeline, what should the automation do?
If your site ships through GitHub Actions, GitLab CI, Jenkins, or similar, validate the sitemap in the same pipeline that deploys the site. That lets you stop bad URLs before they go live, which is far better than asking Search Console to tell you later.
A practical pipeline usually has five steps:
- Build or regenerate the sitemap from the current branch or release candidate.
- Parse the XML and fail on malformed tags, duplicate URLs, or invalid namespaces.
- Extract every listed URL and request it with a `HEAD` or `GET` check, depending on how your origin responds.
- Verify status codes, canonical tags, `noindex`, and robots.txt rules for each URL.
- Block deployment if the error count crosses your threshold, such as any 4xx/5xx or any URL that is no longer canonical.
That flow works well with common tools. For XML parsing and HTTP checks, people often use Python with lxml, requests, and xml.etree.ElementTree, or Node with fast-xml-parser and fetch. For crawling and bulk validation, Screaming Frog SEO Spider has an API and command-line options in paid editions, while Sitebulb and similar crawlers can also fit into a scheduled QA process. In CI, a crawler should usually support the validator rather than replace it entirely.
The trade-off is speed versus certainty. A HEAD request is fast, but some servers treat it differently from GET, so if you rely on it, confirm the behavior with your technical team and the HTTP semantics in the HTTP status code registry. A GET is slower, but it more closely matches how browsers and bots see the page. If your site returns inconsistent headers on HEAD, then use GET and accept the extra time. A 5,000-URL sitemap can turn a quick check into several minutes of pipeline time, so parallel requests matter.
A sane implementation order looks like this:
- Generate the sitemap from the deployed build artifact, not from a stale cache.
- Run an XML schema-style sanity check: root element, namespace, escaping, and URL count.
- Deduplicate URLs and normalize trailing slashes, protocol, and host rules.
- Request each URL and store status, canonical target, robots status, and final destination.
- Compare the live results against a policy file that says what is allowed.
- Fail the pipeline on hard errors, and warn on soft issues like redirected URLs if you are still cleaning up legacy paths.
Quick check: if a broken URL could reach production in under an hour, put this in CI/CD.
How do I automate XML sitemap validation after site changes without a full deployment pipeline?
You automate it with an event trigger plus a lightweight validator if your site changes through a CMS, webhooks, or scheduled publishing jobs. That is the right path when content editors can create URL drift outside a developer release.
In that setup, the trigger should fire after publish, page update, or URL change. The validator should pull the sitemap file, parse it, and check only the URLs touched by the change set when possible. If your CMS exposes the changed slug, page ID, or locale, use that as the seed list. That keeps the job fast and makes the result actionable.
A common stack is a webhook from WordPress, Drupal, Contentful, Sanity, or another CMS into a small service or serverless function. The function reads the sitemap URL, parses the XML, and validates only the changed URL plus its alternates. If the site uses hreflang, the job should inspect each locale version, not just the default language. If it uses multiple sitemap files, validate the index first, then each child sitemap that changed.
Do not wait for Google Search Console as the first line of defense. Search Console is useful, and Google documents sitemap reporting there, but it is not a real-time alerting system. By the time it reports a problem, your bad URLs may have been live for days.
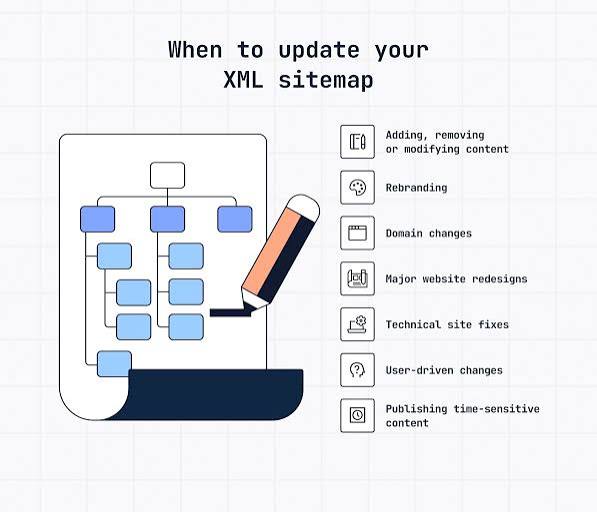
This is the point where many generic guides go wrong: they recommend checking only that “the sitemap exists.” That misses the real failure modes after site changes, such as a page moving from /products/widget-a/ to /shop/widget-a/ while the sitemap still points to the old location, or a CMS template adding noindex to a page that is still listed in the XML.
A workable event-driven path:
- Fire a webhook when content is published or a slug changes.
- Queue a validator job so an editor does not wait on a slow crawl.
- Fetch the current sitemap or sitemap index for the affected section.
- Check that the changed URL appears once, in the correct host and protocol.
- Confirm the URL returns 200, is not blocked, and canonicals to itself or to the intended final URL.
- Send the result to Slack, email, or your incident tool with the exact failure type.
Quick check: if editors can change URLs without a deploy, you need webhook-driven validation, not just CI.
Which validation rules catch the failures that matter most?
The rules that matter most are the ones that map to how search engines treat a sitemap: live URLs, canonical URLs, crawlable URLs, and a clean XML file. If you automate only one thing, automate those four.
Here is the minimum rule set I would use:
- XML is valid and the sitemap index, if present, points to live child files.
- Every listed URL returns 200 or another status you intentionally allow.
- The final URL after redirects matches the canonical you expect.
- The page is not
noindex. - Robots.txt does not block the page.
- The URL is on the correct host and protocol.
- Alternate language or regional URLs in hreflang sets are complete and reciprocal.
- The sitemap contains only canonical URLs, not filtered parameters, print views, or test paths.
The honest trade-off is that every extra rule increases false positives. For example, some sites intentionally keep a redirecting URL in the sitemap during a migration window, and some teams tolerate temporary noindex on staging-like content that later becomes indexable. If that is your case, put those exceptions in a policy file rather than weakening the validator. Policy beats tribal memory.
A few tools help here. Google Search Central documents sitemap format and limits, while the Sitemaps protocol gives the baseline XML rules. For HTTP semantics, the HTTP status code registry is the right reference. For indexing and crawl control, Google Search Central’s documentation on robots.txt and noindex is worth keeping nearby.
A validation rule set becomes much more useful when it is versioned alongside the site. If the product team launches a new subdomain, the validator should learn that rule in the same pull request as the routing change.
Quick check: if a URL is “technically live” but still wrong for SEO, you need canonical and indexability checks, not just status codes.
Edge cases where the normal advice breaks down
The normal advice breaks down when the sitemap is not a simple list of static pages. In those cases, the validator needs context, not just a crawl.
-
Large site migrations
- Situation: thousands of URLs change at once.
- What changes: redirect chains become normal for a short period, and some old URLs may remain intentionally listed during cutover.
- What to do instead: validate by section, keep an allowlist for temporary redirects, and enforce a hard cutoff date. Use a staged rule file, not a blanket pass.
-
International sites with hreflang
- Situation: the same content exists in multiple languages or regions.
- What changes: one broken alternate can damage the whole cluster.
- What to do instead: validate reciprocity across every alternate URL and confirm each locale sitemap points to the correct host.
-
JavaScript-heavy rendering
- Situation: the page content and canonical tags are rendered client-side.
- What changes: a simple HTTP fetch may not see the final canonical or indexable content.
- What to do instead: use a renderer-aware check such as a headless browser step, or validate the server-rendered output if that is what search engines receive.
-
Staging, preview, or password-protected environments
- Situation: non-public environments generate sitemap-like files.
- What changes: status 200 does not mean indexable, and you may not want the validator to treat blocked access as a production failure.
- What to do instead: separate staging rules from production rules, and keep the production sitemap out of preview checks.
-
Soft 404s and thin pages
- Situation: the page returns 200 but contains almost no meaningful content.
- What changes: the sitemap looks fine while the page is still a poor index candidate.
- What to do instead: add content-signature checks, such as template or text-length thresholds, if thin pages are a known risk.
Quick check: if your site has migrations, locales, or client-side rendering, the validator needs exceptions and richer page checks.
What should I monitor after the validator runs?
You should monitor failure type, frequency, and time-to-fix, because a validator that breaks silently is just decoration. If your system catches errors but nobody sees them for 24 hours, the setup is too weak.
The simplest useful dashboard tracks three things: malformed XML, non-200 URLs, and indexability mismatches. If those three stay clean, then most sitemap issues are under control. If you want one more metric, track the number of URLs in the sitemap that changed since the last successful validation. That helps spot mass edits, bad deploys, and accidental deletes.
I would send failures to the place where the owner already works: Slack for editorial sites, Jira or Linear for product teams, PagerDuty or another incident tool for urgent production issues. The message should say exactly which URL failed and why. “Sitemap invalid” is too vague to fix quickly.
A good rule is to separate blocking failures from warnings. A 404 in production is blocking. A single redirect in a migration window may be a warning. A noindex on a key money page is blocking. A temporary staging URL in a non-production environment may not be. That distinction matters because teams stop trusting alerting systems that cry wolf.
Quick check: if nobody can tell what failed, where, and who owns it, the monitoring is not done.
FAQ
How often should I validate XML sitemaps?
After every site change that can affect URLs, plus a scheduled full run at least daily for active sites. If your release cadence is weekly, a post-deploy check may be enough; if editors publish constantly, run on every publish event.
Should I validate the sitemap file or the URLs inside it?
Both. A syntactically valid XML file can still list dead, blocked, or non-canonical URLs.
Is a 301 redirect in a sitemap always wrong?
Usually yes, because the sitemap should list the final URL. During migrations, I would allow redirects only as a temporary exception with an explicit end date.
Do I need Google Search Console if I already automate this?
Yes, but as a backstop, not your primary alert system. Search Console helps catch issues that slip through, and Google’s sitemap reports can confirm what was discovered after the fact.
Drafted with AI; not yet reviewed by a person.