Last updated: October 11, 2026
Key Takeaways
- Start with repeatable reporting, crawl checks, and QA before automating strategy.
- The strongest early automations usually save weekly time and cut preventable errors.
- Automated SEO workflows should begin with inputs, not with software choices.
- Screaming Frog is a strong fit for fast, hands-on technical checks.
Quick Answer: The best starting point for SEO Workflows & Tools for Automation — The Complete Guide is usually 3 core automations: reporting, crawling, and QA. SEO automation is most useful when it removes repetitive work without blinding you to judgment calls. I write about search systems, content operations, and analytics because the wrong automation can make a site faster at publishing the wrong thing. The real question is not “which tool automates SEO?” It is “which workflow should I automate first, with what stack, and where should a human still decide?”
The question that matters: what should you automate first?
Start with data collection, reporting, and repetitive QA, not strategy. That is usually the safest place to use SEO workflows and tools for automation because those tasks are rule-based, measurable, and easy to audit. Keyword clustering, rank tracking, broken-link checks, meta-tag validation, and sitemap monitoring are all better automation candidates than intent analysis or topic selection.
That order matters because most SEO failures come from mixing up “fast” with “smart.” A crawler can surface 10,000 URLs, but it cannot tell you which 200 deserve content rewrites this quarter. A reporting script can pull Search Console data every morning, but it cannot decide whether a page needs consolidation or a new internal-link path. I would automate anything that repeats the same way every week and produces the same output format.
The practical split is simple:
- Automate: crawling, change detection, dashboards, alerts, metadata checks, redirects, content inventory, indexing status reviews, and basic keyword grouping.
- Keep human: search intent, page purpose, information architecture, content briefs, cannibalization calls, and final prioritization.
If you are managing a small site, that may mean one spreadsheet, one crawler, and one dashboard. If you are managing a large catalog or publisher site, it may mean scheduled crawls, API pulls, and workflow tickets routed into a project tracker. The right stack depends less on “best tool” and more on how many URLs you change per week and how many people touch those URLs. For an overview of workflow management, see Google Search Central and this guide’s section on what tools belong around the crawler.
A useful rule: if the task can be described as “compare A to B against a fixed rule,” automate it. If the task is “decide what the user needs next,” do not hand that to software.
Which SEO tasks are worth automating first?
The best first automations are the ones that save time every week and reduce avoidable errors, and in practice they usually fall into this order: reporting, crawling, QA, then content support.
Reporting comes first because it is pure repetition. Search Console exports, Analytics summaries, rank snapshots, and annotation logs are easy to standardize. A weekly dashboard can tell you which pages lost clicks, which queries changed, and which folders are drifting. That makes it easier to spot problems before they become expensive.
Crawling is next because it catches technical issues that humans miss at scale. Tools like Screaming Frog, Sitebulb, and enterprise crawlers can flag noindex tags, redirect chains, duplicate titles, thin pages, and canonical mismatches. A scheduled crawl every 7 or 14 days is often enough for sites that update frequently. For larger sites, crawl sampling and segmented crawls usually work better than a full-site crawl every time. For a tool comparison, see Screaming Frog or Sitebulb: which crawler fits the job?.
QA automation matters because SEO errors repeat. If your CMS can publish a page with a blank meta description, missing H1, or broken canonical tag, someone should be checking that automatically before publish. This is where templates, validation rules, and pre-publication checks save real labor.
Content support is useful, but narrower than people expect. Automation can help group keywords, extract entities, generate brief outlines, and flag internal-link opportunities. It should not be allowed to write strategy by itself. A clustering tool can say that five queries belong together; it cannot decide which page should own that topic without reading the site’s business model and content history.
The part most generic articles skip is this: automation works best when the output is actionable inside the same day. A weekly “SEO insights” PDF is less valuable than an alert that a page noindexed itself after deployment. I would rather have one sharp workflow than five vague ones.
What an automated SEO workflow actually looks like
An automated SEO workflow starts with inputs, not tools. The input might be crawl data, Search Console APIs, analytics events, CMS fields, log files, or a list of target URLs. The output should be a decision or a task, not just a spreadsheet.
A practical workflow usually has five layers:
- Collect
- Normalize
- Detect
- Route
- Review
1) Collect
This is the part that gathers data on a schedule. Typical sources include Google Search Console, Google Analytics 4, server logs, XML sitemaps, a crawler, and your CMS. A site with 5,000 URLs can usually run on scheduled exports. A site with 500,000 URLs often needs API pulls or database syncs. For platform guidance, Google’s documentation at Search Central is the authoritative starting point.
2) Normalize
Different tools name the same thing differently. One source may call a page “URL”; another may split it into path and parameters. One may record impressions by page-query pair; another by page alone. Normalization turns that mess into one clean table. Without this layer, automation becomes a pile of mismatched columns.
3) Detect
This is where the rules live. Detect broken links. Detect pages that lost clicks by more than a chosen threshold. Detect title tags over a character limit. Detect pages with duplicate canonicals. Detect published URLs that are missing from the sitemap. Detection should be rule-based and explicit. If no one can explain the rule in one sentence, it is not ready for automation.
4) Route
Routing turns an alert into an action. A missing title tag can become a CMS ticket. A redirect chain can become a developer task. A page losing traffic can become a content review assignment. Routing matters because warnings that sit in a dashboard are easy to ignore. If you use a workflow tool, make sure it connects to a tracker such as Jira, Asana, Monday.com, Trello, or an equivalent system your team already checks.
5) Review
Humans review the exceptions. Automation should make the exception list shorter, not remove review entirely. The strongest SEO operations I see are often the ones where the machine handles the 90% case and the specialist handles the 10% that needs judgment. Google’s own documentation on search quality and indexing behavior supports the idea that automated checks need human interpretation, especially when changes affect visibility in search.
A workflow like this does not need expensive software to start. A CSV export, a crawler, a spreadsheet, and a ticketing system can cover a lot of ground. More advanced teams can add APIs, data warehouses, and scheduled scripts. The tools matter, but the sequence matters more.
Screaming Frog or Sitebulb: which crawler fits the job?
Screaming Frog wins for operators who want speed, control, and familiarity with technical SEO checks. Sitebulb wins for teams that want more visual reporting and more guided interpretation. I would choose Screaming Frog for lean technical teams and Sitebulb for consultants or in-house marketers who need to explain findings to non-specialists. If you want the vendor pages themselves, see Screaming Frog and Sitebulb.
Screaming Frog is strong because it behaves like a power tool. It can crawl large sites, export targeted datasets, validate canonicals, titles, response codes, directives, and structured data, and integrate with APIs for richer audits. Its strength is not polish; it is precision. If you know what you want to check, it gets out of the way.
That same quality is also its main limitation. Screaming Frog is not trying to interpret your site for you. If a junior marketer opens it without a checklist, they can stare at thousands of rows and miss the one pattern that matters. It rewards process discipline. That makes it less friendly for teams that want a guided narrative.
Sitebulb takes a different path. It packages crawl findings into visual explanations, hints, and issue groupings that help a broader team understand the problem. That is useful when an SEO has to show a content manager why 300 pages are duplicating titles or why internal linking is inconsistent across a section. The reporting layer is the point.
The trade-off is that more explanation can mean less raw control. Teams that live in exports, filters, and repeatable audits may find the presentation layer slower than they want. Sitebulb is not a weakness; it is just less bare-metal.
Here is the practical split: if you need custom filters, fast exports, and a crawler that fits into scripted workflows, choose Screaming Frog. If you need a clearer story for audits, stakeholder reviews, and issue prioritization, choose Sitebulb. Neither is a replacement for judgment. Both become far more valuable when they sit inside a defined audit routine.
The honest side-by-side
The real difference is not “which tool is better.” It is “which workflow does the tool support without extra friction?” Here is the comparison I would use before buying either one.
| Criteria | Screaming Frog | Sitebulb | Winner for this condition |
|---|---|---|---|
| Primary strength | Fast technical crawl exports and granular control | Visual issue grouping and guided reporting | Screaming Frog for technical operators |
| Best user | SEO specialist comfortable with filters and exports | Consultant or in-house marketer explaining issues to others | Sitebulb for stakeholder-facing audits |
| Learning curve | Steeper if you are new to crawlers | Gentler for teams that want interpretation | Sitebulb for mixed-skill teams |
| Workflow fit | Strong in scripted, repeatable technical checks | Strong in presentation-heavy audits | Screaming Frog for automation-heavy setups |
| Reporting style | Export-first, highly configurable | Narrative and visual | Sitebulb for non-technical presentation |
| Speed of hands-on analysis | Efficient once you know the filters | Efficient when you want guided issue discovery | Screaming Frog for experienced users |
| Risk of overwhelm | Higher if the user lacks a checklist | Lower, but with less raw depth at first glance | Sitebulb for first-pass reviews |
| Best for recurring QA | Excellent for scheduled technical audits | Good, but more often used as a review layer | Screaming Frog for repeatable QA |
| Best for client communication | Adequate, but often needs extra packaging | Stronger out of the box | Sitebulb for reporting to others |
The table hides an important truth: the best crawler is the one your team will actually schedule and review every week. A technically stronger tool that sits unused is worse than a simpler one that becomes part of the process. That is why I would not buy either crawler on feature lists alone. I would buy the one that matches the person who will own the audit calendar.
There is one more trade-off worth saying plainly. Screaming Frog is often the better fit if you plan to connect SEO checks to spreadsheets, APIs, or scripts. Sitebulb is often the better fit if the main output is an audit deck or issue report. If your job is “catch and route technical problems,” Screaming Frog has the edge. If your job is “help the rest of the company understand the problem,” Sitebulb is easier to defend.
What tools belong around the crawler?
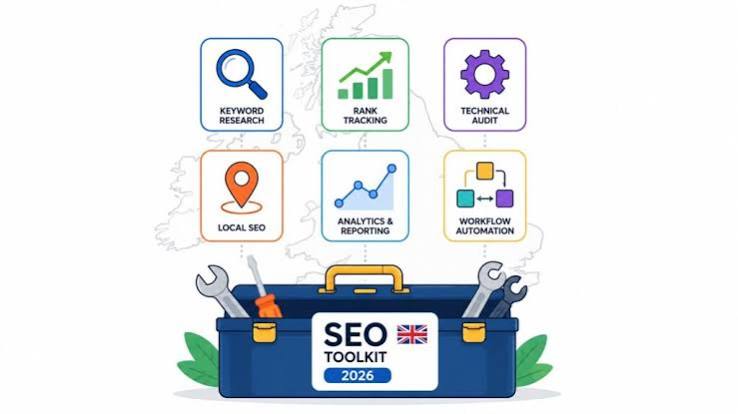
The crawler is only one piece. The useful stack around it usually includes Search Console, a BI dashboard, a ticketing system, and a spreadsheet or database layer. That combination is more practical than chasing a single platform that claims to do everything.
Google Search Console should be the anchor because it is the closest thing many SEO teams have to source-of-truth performance data. It shows query and page performance, indexing signals, and coverage issues. For automation, it works well as an API source for change detection and alerts. If you do nothing else, schedule a recurring review of pages that lost clicks, pages with indexing problems, and query clusters that shifted. Google’s support article at Search Console Help is still the main reference for those reports.
A dashboard tool such as Looker Studio, Power BI, or Tableau is useful only if it turns raw data into a repeatable decision view. A dashboard that nobody opens is decoration. A dashboard that shows weekly lost clicks by template, status code changes, and index coverage by folder is useful. The key is not the brand; it is the question the dashboard answers.
Ticketing systems matter more than people expect. Jira, Asana, Monday.com, Trello, or a comparable workflow tool gives automation a place to land. If a redirect needs a developer, it should become a ticket. If a page needs a rewritten title, it should become a content task. Without routing, automation stops at detection.
For heavier operations, a database or warehouse layer becomes valuable. BigQuery, Snowflake, or even a structured SQL database can unify crawl data, Search Console exports, analytics, and log files. That matters when you need historical comparisons across months and templates, not just one-off audits.
The trade-off is complexity. Every added layer increases maintenance. More tools mean more credentials, more mappings, and more places where data can drift. I would not add a warehouse just because it sounds advanced. I would add one when the team needs queryable history and cannot keep up with CSV sprawl.
When should automation stop and a human take over?
Automation should stop when the next step changes the meaning of the data. That is the line I use.
If a page drops 30% in clicks, automation can flag it. It cannot know whether the reason is seasonality, SERP format changes, intent shift, a competitor update, or an internal linking problem. A human has to inspect the page, the query set, the SERP, and the content intent.
If two URLs rank for the same query cluster, software can identify the overlap. It cannot decide whether to consolidate, canonicalize, redirect, or keep both live. That depends on the site’s architecture, backlinks, business goals, and content quality.
If a crawler finds 1,000 duplicate titles, automation can group them by pattern. It cannot decide whether the issue comes from a bad template, a parameterized URL set, or a legacy section that should be removed. That is diagnosis, not detection.
This is where many teams go wrong. They automate reporting and assume they have automated decision-making. They have not. They have only made it easier to see the problem. That is still worthwhile, but it is not the same thing.
I would hand control back to a human in four situations, and if the issue affects revenue pages or top landing pages, it is wise to consult a professional before making changes:
- the issue affects revenue pages or top landing pages,
- the fix could create crawl or indexing side effects,
- the pattern suggests multiple causes,
- the answer will change based on business priority, not just SEO logic.
That boundary keeps automation honest. It also prevents a common failure mode: teams over-trusting alerts and under-investing in diagnosis. For technical governance, Google Search Central and its related documentation remain the safest reference point.
The exception scenarios that change the verdict
The overall recommendation flips in a few situations. If one of these is true, I would change the stack.
First, if the site is tiny — say under a few hundred URLs — full automation can be overkill. A crawler, Search Console, and a spreadsheet may be enough. In that case, buying a more advanced reporting layer before the workflow exists is premature.
Second, if the team is mostly non-technical, Sitebulb becomes easier to justify than a lower-level crawler because the visual output reduces interpretation friction. A simpler explanation is often more valuable than a deeper export.
Third, if the site changes daily across many templates, automation must move closer to the CMS and ticketing system. In that setting, pre-publish checks and release QA matter more than monthly audits. A crawler alone will always be late.
Fourth, if the organization already has a strong BI stack, the crawler should plug into that system rather than start a parallel reporting habit. Otherwise, two dashboards will compete for attention, and both will be ignored.
Those are not minor edge cases. They are the difference between a workflow that sticks and one that becomes shelfware after the first month.
The verdict: which automation stack I would choose
Choose Screaming Frog if you need a technical crawler for scheduled QA, custom exports, and repeatable audits. Choose Sitebulb if you need a clearer reporting layer for mixed-skill teams and client-facing explanations. Neither if you do not have someone responsible for reviewing the output every week.
That is the practical answer. The right SEO automation stack is not the one with the longest feature list. It is the one that fits the workflow you can maintain with the people you already have. If you need to detect, route, and fix technical issues at scale, start with a crawler, Search Console, a dashboard, and a ticketing system. If you need help deciding what a finding means, add visual reporting. If you need content strategy, keep that human. For setup ideas, revisit what tools belong around the crawler and what an automated SEO workflow actually looks like.
Sources and further reading
For the rules around crawling, indexing, and diagnostics, I would start with Google Search Central:
- https://developers.google.com/search/docs
- https://support.google.com/webmasters/
For structured site management and technical standards, the following are useful references:
- W3C technical standards: https://www.w3.org/standards/
- Search Console help documentation from Google Search Central: https://support.google.com/webmasters/
FAQ
What is the first SEO task I should automate?
Start with reporting or crawl-based QA. Those tasks repeat on a schedule and have clear rules, which makes them safer to automate than strategy or intent work.
Can SEO automation replace an SEO specialist?
No. It can remove repetitive checking and speed up detection, but it cannot choose priorities, interpret search intent, or decide trade-offs between pages.
Is Screaming Frog or Sitebulb better for beginners?
Sitebulb is usually easier for beginners because it explains issues more clearly. Screaming Frog is better when the user already knows which technical checks they want.
Do I need a database or warehouse to automate SEO?
Not at the start. A small team can go far with exports, spreadsheets, and scheduled reports. A warehouse becomes useful when the site size or history makes CSV workflows too messy.
What should I never automate fully?
I would not fully automate content strategy, page consolidation decisions, or fixes that can change indexing behavior without review. Those choices still need a human owner.
Drafted with AI; not yet reviewed by a person.