Last updated: October 11, 2026
Key Takeaways
- Large faceted catalogs can explode into millions of crawlable URL combinations.
- The usual rule stack is discover, classify, prioritize, then suppress waste.
- For ecommerce, keep product and category URLs first, and reduce low-value filter variants.
- Use logs, Search Console, a crawler, and rules together; no single tool shows the full picture.
Automating crawl budget management means using rules, logs, and crawl controls to make search bots spend time on pages that matter and waste less time on duplicates, dead URLs, and low-value parameter traps. This article on Automating crawl budget management covers the practical answer for sites with more than a few thousand URLs, frequent content changes, or weak server headroom: how do I keep Googlebot focused without babysitting every crawl issue?
Quick answer: for most sites, automation should aim to cut wasted crawl by 20% to 50% while protecting product, category, and fresh content URLs. In practice, that means using rules, logs, and crawl controls to keep search bots on pages that matter.
What actually determines the right answer here?
The right answer is usually not “crawl everything” and it is not “block as much as possible.” It depends on how fast your site changes, how many URLs can be reached from internal links, and whether your server can absorb bursts from bots without slowing down users.
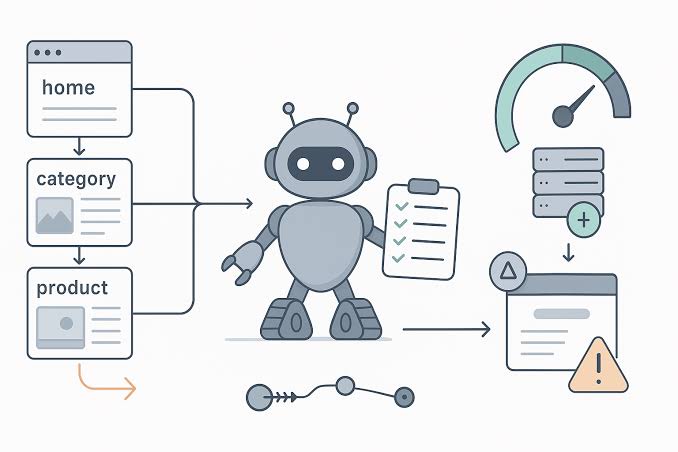
For example, if you run an ecommerce catalog with faceted navigation, the problem is usually explosion: one product grid becomes millions of crawlable combinations. If you run a news site or a large publisher, the problem is freshness: new URLs should be discovered and revisited fast, while archive pages should not crowd them out. If you run a SaaS site with a few hundred pages, crawl budget is often a small issue unless you have duplicate app routes, staging leaks, or endless query strings.
Automating the job works best when you turn crawl control into rules instead of ad hoc fixes. The main levers are still the same:
- internal linking
- XML sitemaps
- robots.txt
- canonical tags
- noindex where appropriate
- server log analysis
- removing trap URLs from navigation and parameter handling
Because each lever does a different job, the trade-off is simple: the more aggressively you prune crawl paths, the more careful you must be not to block pages that need discovery or consolidation. A blanket disallow can solve waste and create indexation gaps in the same move.
Here is the working decision table I would use first:
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Millions of URL variants from filters | Parameter rules, noindex on thin variants, canonical to the clean version, and internal-link pruning | “Let Google figure it out” burns crawl on junk and delays important pages |
| Fresh content with lots of old archives | Strong sitemaps, recrawl prioritization, and tighter internal links to new pages | Blocking archives too hard can hide context and break discovery |
| Small site with duplicate routes | Fix architecture first, then simple noindex/canonical rules | Heavy automation is overkill and can introduce accidental exclusions |
| Slow server under bot load | Rate control through hosting, caching, and crawl reduction at the source | Robots rules alone do not fix latency if the bot still reaches expensive URLs |
Quick check: if your issue is duplicate URL growth, freshness, or bot-induced load, automation can help; if your problem is simply weak site architecture, start there first.
How do I automate crawl budget management without breaking indexing?
You automate it by turning crawl signals into a rule stack: discover, classify, prioritize, then suppress waste. That order matters. If you suppress first, you can hide pages before search engines have enough signals to understand the site.
The cleanest automation path usually starts with logs and ends with controlled crawl surfaces.
- Collect server logs for at least 14 days so you can see what Googlebot, Bingbot, and other crawlers actually request, not what you assume they request.
- Classify URLs by purpose: money pages, indexable supporting pages, duplicate variants, and trap URLs created by parameters, internal search, or sort orders.
- Map crawl spend to value using log hits, response codes, canonical targets, and index status in Google Search Console.
- Fix internal links first so the clean version gets the strongest signals. If your template links to 12 filter combinations, no amount of robots.txt polish will save you.
- Add rules for patterns that never deserve crawl: internal search results, endless sort permutations, session IDs, and print pages. Use robots.txt for crawl exclusion, not for index removal.
- Use noindex for pages that can be crawled but should not be indexed, such as thin paginated subsets or duplicate landing pages you still want bots to reach once.
- Consolidate with canonicals where duplicates must remain live. Canonical is a hint, not a force field, so keep the duplicate set small and consistent.
- Validate changes in crawl stats and logs over 2–4 weeks. Automation that never gets checked is just a way to automate mistakes.
The best tools here are the familiar ones that are boring but effective: Google Search Console, raw server logs, Screaming Frog, Sitebulb, Logz.io or another log pipeline, and a crawler that can respect robots directives. For larger sites, bot-management layers at the CDN or WAF level can help reduce waste, but I would treat those as pressure relief, not the core strategy; a specialist should review that setup, and Cloudflare’s bot management guidance is a useful starting point.
If you want a standards anchor, I would read Google’s robots.txt documentation and its Search Central guidance on crawl budget before writing any rule set. I would also keep the RFC 9110 HTTP status codes in mind when diagnosing 3xx chains, 4xx noise, and server responses.
Useful references: Google Search Central robots.txt documentation and Google Search Central crawl budget guidance.
The main limitation is that automation cannot guess business value. A URL with few links may still matter if it drives revenue or supports an important query cluster. That is why the rule set has to be paired with a page inventory from someone who knows the business.
Quick check: if you can name the URL patterns you want crawled less, and the ones you absolutely need crawled more, then you are ready for automation; if you cannot, you need a page classification pass first.
If you’re in ecommerce, here’s the crawl strategy I would use
If you run ecommerce, I would prioritize product and category URLs, then suppress filter combinations that do not create distinct search value. The standard advice that says “just canonical everything” is too blunt for large catalogs, because canonicals do not prevent crawl, and crawl is the thing wasting your budget.
For ecommerce, the usual culprits are sorting, color, size, brand, price sliders, and internal search pages. If these combinations create near-infinite paths, Googlebot can spend days in the weeds while new product pages wait for discovery. In that case, the strategy should be selective, not universal.
A practical path looks like this:
- Identify the canonical money pages: categories, subcategories, and products that convert or support strong non-brand demand.
- Restrict crawlable filters so only combinations with search demand or merchandising value are linked in HTML.
- Block crawl traps in robots.txt only when the pattern is clearly useless, such as internal search results or session parameters.
- Use canonical tags on duplicate sort or tracking variants, but do not rely on canonicals to clean a parameter maze you still expose everywhere.
- Keep XML sitemaps focused on high-value URLs and refresh them often enough that stale SKUs and empty filtered pages do not dominate them. Google’s sitemap guidance is clear that sitemaps help discovery, not ranking.
- Watch for soft 404s, faceted dead ends, and 3xx chains because they consume crawl without helping indexation.
- Review log samples every month to see whether bot traffic is shifting toward the right sections after your changes.
Because those filter combinations can create accidental duplicates, I would not recommend heavy-handed noindexing of core product pages unless they are truly dead, out of stock long term, or duplicates of another live offer. If you noindex too much, you can accidentally starve discovery of important products and categories. The better move is usually to reduce the number of crawlable variants, not to hide the whole catalog.
One concrete benchmark that matters here is response time. A page that takes multiple seconds to render under bot load will limit effective crawl far more than a neat sitemap ever will. If your origin is slow, fix caching and TTFB before you spend weeks on canonical tuning.
Quick check: if your crawl logs show repeated hits to filters, sorts, and internal search, your first fix is URL control and linking, not more content.
What tools should I use, and what do they actually do?
You should use logs, a crawler, Search Console, and a rules layer, because no single tool shows the full picture. Each one tells you something different, and the wrong one alone leads to bad decisions.
Here is the short version of what each tool is for:
- Google Search Console: shows crawl stats, index coverage, and URL inspection signals.
- Server logs: show real bot behavior, which pages bots request, how often, and how they respond.
- Screaming Frog or Sitebulb: find link graphs, canonical issues, redirect chains, duplicate titles, and parameter sprawl.
- CDN/WAF tools such as Cloudflare or Fastly: can help reduce repeated bot hits and protect origin resources.
- Analytics and tag managers: help identify pages that matter commercially, which should influence prioritization.
- Enterprise SEO platforms such as Botify, Lumar, or similar log and crawl suites: useful when the URL count is too large for manual checks.
The mistake I see most often is treating a crawler report as proof of crawl budget problems. A crawler can tell you that a site has 200,000 URLs; it cannot tell you which of those URLs Googlebot actually spends time on until you combine it with logs and Search Console. That distinction matters, and Google’s own crawl budget guidance supports the log-first approach.
Use this stack in order:
- Start with Search Console to spot crawl spikes, indexing drops, and URL inspection patterns.
- Pull logs to confirm whether Googlebot is hitting duplicate patterns, dead URLs, or expensive endpoints.
- Crawl the site to find the structure that is creating those URLs in the first place.
- Cross-check business priority so you do not accidentally protect low-value sections just because they are noisy.
- Implement rules at the source: templates, navigation, parameters, robots, canonical, and sitemap generation.
- Re-audit after deployment with a 2-week and 4-week checkpoint.
The honest trade-off against the obvious alternative is cost and complexity. A simple site may only need Search Console plus a crawler. A large marketplace usually needs logs and automation tooling because manual review does not scale past a few tens of thousands of URLs. If you do not have that scale, buying an enterprise platform too early can be wasted spend.
Quick check: if you are still arguing about “what Google crawled” without logs, you are guessing; if you have logs and a crawl map, you can make decisions.
When the standard advice is wrong
The standard advice is wrong when your site has edge conditions that change the economics of crawling. That usually means one of five things: JS-heavy rendering, multilingual duplication, massive archives, low-host capacity, or legal/compliance constraints on what can be exposed.
JavaScript-heavy sites
If important links only appear after JavaScript runs, then crawl automation must start with rendering, not robots rules. Google can render JavaScript, but not every bot does, and expensive render paths can slow discovery. The fix is to expose key links in plain HTML, or at minimum in the initial server response.
Multilingual or multi-regional sites
If the same content exists across language or country variants, then hreflang, canonicals, and sitemap segmentation matter more than blanket noindex rules. If you mix regions in one crawlable space, bots can waste time on duplicate translation pairs and inconsistent alternates. Separate your signals cleanly.
Huge archive sites
If you have years of archive content, then the answer is not to hide the archive entirely. That destroys topical depth. The better move is to prune low-value tag pages, add stronger hubs, and keep archives discoverable through a smaller number of high-signal paths.
Sites under resource strain
If your server is already slow, then crawl budget management is partly an infrastructure job. Fix caching, reduce expensive database queries, and close bot loops before you try to micromanage Googlebot. A 1.5-second slowdown on critical templates can matter more than another sitemap tweak.
Compliance-sensitive sites
If URLs expose data you cannot afford to have indexed or broadly crawled, then crawl control alone is not enough. You need access control, not just SEO controls. Robots.txt is not a security feature.
The general rule is simple: if the problem is discovery, change links and sitemaps; if the problem is waste, block or consolidate; if the problem is load, fix infrastructure; if the problem is sensitivity, restrict access.
Quick check: if your site has JavaScript rendering, international duplication, or compliance limits, the normal “just canonical it” advice is probably too weak.
What does a prioritized crawl strategy look like in practice?
A prioritized crawl strategy means giving bots a hierarchy: crawl the most valuable, most update-sensitive URLs first, then the supporting pages, then the historical pages, and leave trap patterns out of the path. It is the difference between “access” and “sequencing.”
Since crawl priority is really a ranking problem inside the crawl system, I would rank URLs using four factors: business value, freshness demand, link prominence, and duplication risk. Pages with high business value and high freshness demand go first. Pages with weak business value and heavy duplication go last, or not at all.
That usually translates into this order:
- Homepage, top category pages, and major editorial hubs
- New or updated pages with clear search demand
- Supporting pages that strengthen topical authority
- Archive pages and low-traffic long-tail pages
- Duplicate, parameterized, or utility URLs that should be suppressed
The prioritization has to show up in the site, not just in the crawl map. If navigation, sitemaps, and canonical tags disagree, bots will follow the messiest signal. That is why the page hierarchy should be consistent across templates, XML sitemaps, and internal linking.
In practice, the best rollout is usually phased. Start by fixing the biggest source of waste, then measure logs for 2 to 4 weeks, then move to the next pattern. Google’s own documentation says crawl budget is mainly a concern for large, frequently changing sites, so smaller sites should usually focus on cleaner architecture first.
Quick check: if your most important pages are not the easiest ones to reach, your crawl strategy is upside down.
How do I keep the system from drifting later?
Once the rules are in place, drift becomes the real risk. New templates, seasonal collections, and CMS changes can quietly reintroduce the same crawl waste you just removed.
Therefore, automation needs monitoring. Add a monthly review of log samples, a Search Console check for crawl spikes, and a crawl of the highest-risk sections after every release. If you use an enterprise stack, set alerts for sudden increases in parameter URLs, 3xx chains, and soft 404s.
Because teams change over time, document the rules as business logic, not just SEO preferences. A filter may be crawlable because merchandising wants it indexed, or it may be blocked because it produces empty combinations. That distinction should live in the decision record, so the next site change does not undo it by accident.
Once the system is stable, the goal is not perfection. The goal is that your crawl patterns stay aligned with business value, even as the site grows.
Drafted with AI; not yet reviewed by a person.