Last updated: October 11, 2026
Key Takeaways
- Repeatable page types are the easiest place to automate schema and keep it consistent.
- If you skip the core fields, the markup may look valid but behave like noise.
- A practical starting order is Organization, BreadcrumbList, Article, Product, and LocalBusiness.
- If you are on WordPress, Shopify, or a headless CMS, the right approach depends on the rendering layer.
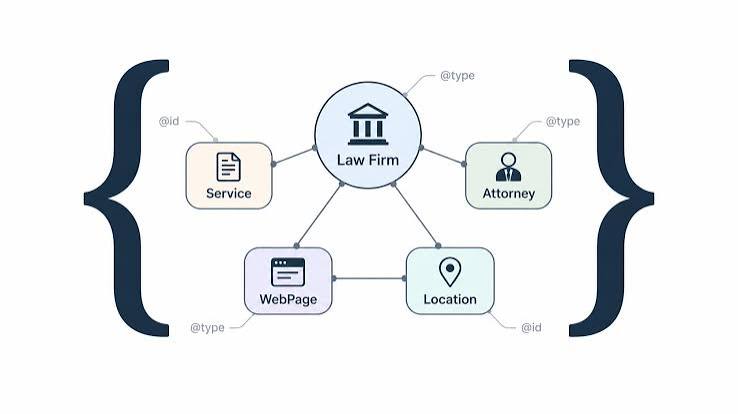
Automating schema markup generation across your site means I can stop hand-writing JSON-LD on every page and instead generate the right structured data from the fields your site already stores. If your site has more than a few dozen pages, that is usually the right move; if your pages are highly custom, it can backfire fast. For a broader technical overview, see Google Search Central and the Schema.org Structured Data documentation.
What Actually Determines the Right Answer Here
If your site has repeatable page types, then automation is often the cleanest way to keep schema markup consistent without turning every content edit into a developer task. If your pages all behave differently, the answer flips: template-based automation will miss edge cases, and a partial setup is better than a fake “sitewide” one.
The real question is not “Can schema be automated?” It is “Which parts of schema can be safely generated from known fields?” For many sites, the answer is most of the boring pages: articles, product pages, FAQs, local business pages, breadcrumbs, and organization data. Those map well to content models in WordPress, Shopify, headless CMSs, or a custom database.
A useful rule is simple: automate only when the source fields are stable. If your CMS already stores title, author, published date, product price, SKU, review count, opening hours, or address, you have enough raw material to generate valid JSON-LD. If those fields are missing or unreliable, automation will just spread bad data faster.
Here is the trade-off against the obvious alternative. Manual schema gives you precision for odd pages and one-off campaigns, but it breaks down as soon as content volume grows. Fully automated schema saves time, but it depends on disciplined data modeling and QA. If your team changes templates often, automation can also create false confidence: the markup will exist even when the page no longer deserves it.
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Blog or news site with many similar articles | Template-generated Article schema | Manual markup does not scale and invites drift |
| Ecommerce catalog with stable product fields | Automated Product schema from catalog data | Copy-pasting schema misses price, availability, and variant changes |
| Local business with multiple locations | Location-specific schema from a location database | One global Organization block cannot describe every branch |
| Complex landing pages with custom sections | Hybrid: base automation plus per-page overrides | Pure automation misses special offers, event dates, or unusual FAQs |
Quick check: if your pages share 70% or more of their structure, automation probably fits; if each page needs its own story, it probably does not.
How I’d Automate Schema Markup Step by Step
Because this needs to run across a real site, I would build it in six passes: audit, map fields, choose a schema type, generate JSON-LD in templates, validate, then monitor. If you skip any of those, you usually end up with markup that looks official and performs like noise.
- Inventory your page types. List the templates you actually have: homepage, article, category, product, collection, location, FAQ, event, and any custom landing pages. A site with 8 templates is much easier to automate than one with 80 page-builder variants.
- Map each template to one primary schema type. Use
ArticleorNewsArticlefor editorial content,Productfor product pages,LocalBusinessfor branches,FAQPagefor real Q&A pages, andBreadcrumbListfor navigation. Do not stuff five schema types onto every page just because you can. - Identify source fields in your CMS or database. For example: title, excerpt, author name, publish date, image URL, canonical URL, price, currency, availability, address, phone, and opening hours. If a field is editable by nontechnical staff, document its format now; ISO 8601 dates and full absolute URLs matter.
- Build the JSON-LD in the template layer. In WordPress, this may be a theme hook or plugin filter; in Shopify, a theme section or snippet; in a headless setup, it may live in the front-end rendering layer. Keep the logic close to the template so page data and markup cannot drift apart.
- Add conditional rules. If an author field is blank, omit author rather than inventing one. If a product is out of stock, set availability correctly. If a page has no real FAQ content, do not output FAQ schema at all. Valid schema beats bloated schema every time.
- Validate before and after launch. Check a sample of pages with Google’s Rich Results Test and the Schema Markup Validator from Schema.org. Then inspect rendered HTML, because JavaScript-rendered markup can fail if it is injected too late or blocked by template changes.
- Set a review loop. Recheck after CMS updates, theme changes, taxonomy edits, and product feed changes. A monthly audit is enough for many sites; fast-changing ecommerce catalogs may need a tighter cadence.
If you want the shortest path, automate only the high-volume templates first. A 20-page microsite does not need the same system design as a 20,000-page catalog. The second one does.
Quick check: if your team can point to the exact field that feeds each schema property, you are ready to automate; if they cannot, pause and clean up the data model first.
Which schema types should be automated first?
If you need a priority order, start with schema that repeats cleanly and supports clear page intent: Organization, BreadcrumbList, Article, Product, and LocalBusiness. Those are the easiest to keep accurate because the required fields are usually already in the CMS or store backend.
I would not start with every possible type. Event schema sounds attractive until dates, venues, and cancellations start changing. Recipe, JobPosting, and Course can also become fragile if the editorial process is loose. Automation is only as good as the data source, and some content teams change content faster than they change process.
A practical order looks like this:
- Organization / WebSite — one-time site-level markup, usually sitewide.
- BreadcrumbList — based on URL or taxonomy, useful across many templates.
- Article / NewsArticle — for editorial templates with stable metadata.
- Product — for catalog pages with price, availability, and SKU.
- LocalBusiness — for location pages with address and opening hours.
- FAQPage — only when the page truly contains a Q&A section.
The important trade-off is between reach and precision. Sitewide schema like Organization and BreadcrumbList gives broad coverage with low risk. More specific schema like Product or Event can earn richer results, but it fails harder when the data is incomplete. If a product page lacks reliable price or stock data, I would rather omit Product markup than publish stale details.
If you use WordPress, plugins like Yoast SEO, Rank Math, and Schema Pro can automate some of this without custom code, though they often need template-level tuning. In Shopify, structured data often lives in theme Liquid files or an app, but app-generated markup can conflict with custom theme code. In headless systems, the front end often has to assemble JSON-LD from API fields, which is more work upfront but easier to control long-term.
Quick check: if a schema type depends on fields that change daily or inconsistently, do not automate it first.
How do I automate schema markup in WordPress, Shopify, or a headless CMS?
If you are on WordPress, Shopify, or a headless CMS, the best path depends on the rendering layer and the content model. The common rule is simple: generate JSON-LD as close to the page template as possible, not in a random plugin setting you will forget about in six months.
In WordPress, I would first see whether your SEO plugin already outputs usable markup. If it does, remove duplicate schema before adding custom code. Then use template hooks or a child theme to inject schema from post fields such as title, author, featured image, categories, and published date. For custom post types, map each field deliberately; do not assume the plugin guessed your business model correctly.
In Shopify, theme-level schema often belongs in Liquid snippets or sections. That works well for Product pages because Shopify already exposes product objects, variants, inventory, and pricing in predictable ways. It gets trickier on content pages created with page builders or apps, because the source data can be split across the theme, app, and metafields.
In a headless CMS, the front end usually becomes the schema renderer. That is powerful because you can use the same content API that powers the page to also build the structured data. It is also easy to overcomplicate. If your content model has ten optional nested objects, you need stricter fallback rules than a normal CMS template.
- Choose one rendering point. Put schema generation in the same layer that renders the visible page, not in three places.
- Create a mapping document. Write down which CMS field becomes which schema property. Example:
headline→name,publishDate→datePublished. - Normalize data formats. Dates should be ISO 8601, URLs absolute, and addresses consistent.
- Add fallback rules. If
authoris empty, omit it. If an image is missing, use no image rather than a broken URL. - Prevent duplicate output. Check whether your theme, plugin, app, or custom component already emits schema.
- Deploy with sample-page QA. Inspect at least one page from each template after every major release.
The honest downside is that custom implementation takes engineering time. A plugin can be faster on day one. A template-driven build is usually safer on day 180. If your site changes often and the team has development support, I would choose code over a black-box plugin.
Quick check: if you can explain where the JSON-LD is rendered in one sentence, you probably have the right architecture; if not, you likely have duplicate or hidden schema already.
How do I keep automated schema from going stale?
If your content changes weekly or daily, then schema maintenance matters as much as generation. Automation breaks not when it is first built, but when the source fields drift, new templates appear, or someone edits content in a way the mapper never expected.
The biggest failure mode is stale truth. A product goes out of stock, a location changes hours, a page title changes after a campaign, and the schema still shows the old value. That is not a small cleanup issue; it can make rich results unreliable and erode trust in the markup as a whole.
I would set up four guardrails:
- Schema ownership — one person or team owns the mapping document.
- Template change review — no template ships without schema validation.
- Field-level validation — dates, URLs, prices, and phone numbers are checked before render.
- Periodic audits — sample pages are checked after major content or CMS changes.
A good automation system has escape hatches. For example, an editorial team may need to override the default author, or a product page may need to suppress review markup when ratings are not representative. If every page is forced through the same machine, the machine will eventually publish nonsense.
This is also where external validators matter. Google’s Rich Results Test and the Schema Markup Validator from Schema.org catch different classes of issues. One is about eligibility for rich results; the other checks structured data syntax more generally. I would use both on representative pages, not just the homepage.
Quick check: if schema changes whenever a template changes, and nobody is checking that after release, your automation is already stale.
What breaks the normal advice?
If your site has one of these situations, then the standard “just automate it” advice is wrong or incomplete. These are the cases I would treat differently, and I would have a qualified professional review legal or medical markup before launch.
-
Multiple content sources feed one page.
What changes: data is split across a CMS, a product feed, and a marketing app.
What to do instead: pick a single source of truth for each property and document the conflict rule. If the CMS says one thing and the feed says another, automation needs a priority order. -
Pages are built by drag-and-drop modules.
What changes: the layout is inconsistent, even if the URL pattern is not.
What to do instead: generate only the base schema automatically and leave module-specific extras for manual overrides. A page-builder homepage is not a good candidate for full automation. -
Your legal or medical content needs careful review.
What changes: the cost of incorrect metadata is higher, and schema can imply more certainty than the page deserves.
What to do instead: keep schema minimal and conservative. For anything regulated, have a qualified professional review content and markup before launch. -
You have duplicate templates for the same intent.
What changes: two or more page templates describe the same thing, such as product detail pages with different layouts.
What to do instead: standardize the data model before automating. Otherwise you will maintain two schema systems that slowly diverge. -
The site is multilingual.
What changes: titles, descriptions, and sometimes dates or currency formats vary by locale.
What to do instead: render language-specific JSON-LD tied to the correct locale, and do not copy the primary-language schema into translated pages. -
You rely on heavy client-side rendering.
What changes: structured data may appear too late or not at all if JavaScript fails.
What to do instead: server-render the JSON-LD when possible, or at least confirm that crawlers receive it consistently.
These edge cases are where a generic plugin starts to fail, and they are usually the point where implementation details matter more than the schema type itself.
Drafted with AI; not yet reviewed by a person.