Last updated: October 11, 2026
Key Takeaways
- You need collection, alerting, and ownership before automation pays off.
- Track trends on important routes, not every pageview, to keep alerts useful.
- A good stack needs field data, a routing layer, and a repair queue.
- RUM is strongest when routes change often and attribution matters.
Quick Answer: for most teams, Automate Core Web Vitals monitoring and remediation workflows with 3 parts—field collection, routing, and ownership—plus route-level alerts that can be acted on in one shift.
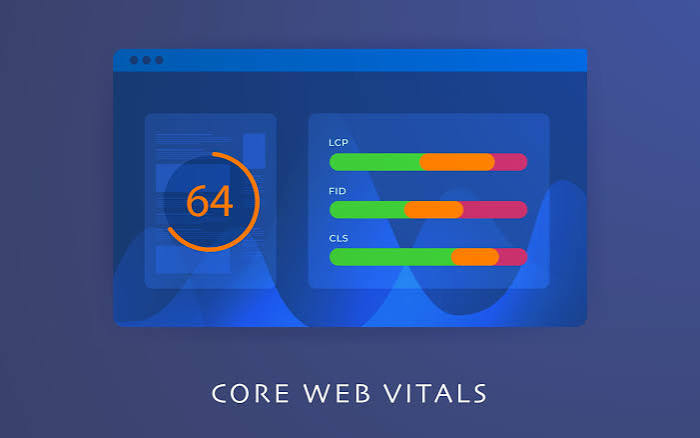
Automating Core Web Vitals monitoring and remediation workflows is for the team that needs pages to stop slipping between releases, not for the team that wants another dashboard. I would set it up when engineering owns performance budgets, SEO needs early warning, and the business cannot wait for a monthly report to discover a bad LCP, INP, or CLS regression. Google’s Core Web Vitals thresholds are specific: LCP should be 2.5 seconds or less, INP 200 milliseconds or less, and CLS 0.1 or less.
I write about web performance and SEO tooling with a bias toward workflows that survive real product teams, not just clean demos. The right setup is usually a mix of field data, alerts, and a remediation path tied to code ownership. For reference, Google’s web.dev Core Web Vitals guide and the Search Console help docs are useful starting points.
What you actually need to automate first
You need three things first: collection, alerting, and ownership. Without all three, Core Web Vitals monitoring becomes a chart that everyone checks and nobody acts on.
The mistake I see most often is starting with a fancy dashboard. That gives you visibility, but not a process. Core Web Vitals are based on field behavior, not just lab runs, so the workflow has to capture real-user data from sources such as the Chrome UX Report, Google Search Console, and a RUM tool like SpeedCurve, New Relic, Datadog, or mPulse. Google’s own guidance is still the standard reference here, and the web.dev Core Web Vitals page is the most useful starting point.
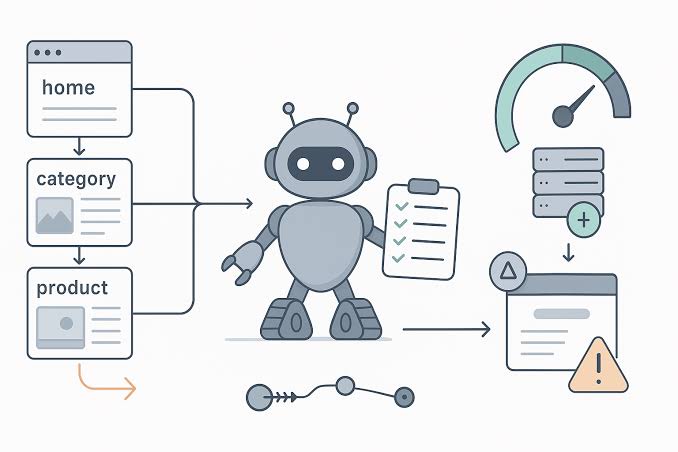
Automation should do two jobs. First, it should detect when a metric moves in the wrong direction. Second, it should route that signal to the person who can fix it. For example, a CSS change that pushes CLS over the line belongs in the frontend backlog; a slow hero image belongs with the media pipeline; a long main-thread task belongs with the feature team that shipped it. If you already use a release calendar, add the deploy timestamp to the alert so the team can compare before and after.
The setup I would choose for most product teams is simple:
- field-data collection at the route level
- alerting on thresholds and trend changes
- a ticket or chat handoff with URL, template, and recent release context
- a post-fix verification step tied to the same route
That sounds basic because it is. The real difficulty is not measurement. It is keeping the signal close to the code that caused it. For teams already using Google Search Console, Jira, or Linear, the win is not more data; it is a cleaner handoff.
How do you automate Core Web Vitals monitoring without drowning in alerts?
You automate it by watching trends, not every bounce, and by alerting on routes that matter. If you alert on every pageview, the system becomes noise within a week.
I would use a two-layer model. The first layer watches aggregate field data daily or hourly. The second layer watches deployment-linked deltas on the pages that drive revenue, signups, or search traffic. A page can be “fine” in a monthly summary and still fail after a release that only affects the checkout route. That is why a release annotation or deploy marker is so useful.
This is where the metric details matter. LCP, INP, and CLS do not fail for the same reasons, so they should not trigger the same response:
- LCP usually points to server latency, large hero media, render-blocking CSS, or late-loading critical resources.
- INP usually points to JavaScript contention, long tasks, or heavy event handlers.
- CLS usually points to images without dimensions, late-inserted UI, fonts, ads, or hydration issues.
Automation should classify the likely root cause before it creates work. Even a simple rule engine helps: if CLS jumps after a layout-heavy release, route the ticket to the frontend owner; if LCP degrades and the HTML response time climbed, route it to platform or backend. According to Google’s own guidance, field data is what matters most for user experience, so the alert should reflect the route and the release, not just a sitewide score.
The best alerting threshold is often the one your team can act on within a single shift, especially when the route is business-critical. That usually means alerting on route-specific regressions, not on the entire site average. If you have 10,000 URLs, the sitewide number can hide a broken template for days. I would rather have 20 precise alerts than 200 vague ones.
The weakness of this approach is maintenance. Someone has to keep the route map current, decide which templates are business-critical, and adjust thresholds as traffic mix changes. If the site changes weekly and no one owns performance hygiene, automation will faithfully surface chaos.
Which tools belong in the stack, and which ones do not?
The monitoring stack should include one source of truth for field data, one alerting layer, and one remediation queue. Anything else is optional.
For field data, I would start with Google Search Console for search-facing visibility and a RUM platform for operational detail. Search Console is useful because it shows how Google groups URLs into good, needs improvement, and poor buckets, though it is not a debugging tool and it updates slowly enough that it cannot be your only signal. Chrome UX Report data is useful for broad trends, but it is sampled and aggregated, so I would not use it as the sole trigger for urgent action. Google says Search Console can lag by days, which is one reason it works best as a direction-setting tool rather than a live pager.
For automation and workflow, the strongest setup is usually:
- a RUM vendor or observability platform for route-level metrics
- a CI or deployment hook to compare new releases against a baseline
- Slack, Microsoft Teams, Jira, Asana, or Linear for ticket routing
- synthetic checks for known critical paths, especially when a release changes template code
I would skip tools that only produce prettier charts than your current stack. If a product cannot tell you which route regressed, which release caused it, and who owns the fix, it is not a remediation tool. It is a reporting tool.
This is where commercial trade-offs show up. A full observability platform often gives you richer tracing and alerting, but it costs more to run in practice because it adds setup time, tag hygiene, and ongoing tuning. A lighter-weight RUM tool may be easier to adopt, but you will spend more time stitching it into tickets and release workflows.
The question is not “which tool is best?” It is “which one can your team keep alive?” A small team with one frontend engineer and one marketer should pick the smallest stack that can still assign ownership. A larger org with multiple squads and frequent releases can justify deeper integration, especially if performance regressions have already caused SEO or conversion problems. For a broader performance baseline, Google’s PageSpeed Insights and web.dev pages can help anchor the discussion.
The honest side-by-side: RUM platform versus lightweight monitoring
A RUM platform wins when the site changes often and the team needs route-level attribution. Lightweight monitoring wins when the main goal is quick visibility with low setup overhead.
| Criteria | RUM platform | Lightweight monitoring | Winner for [condition] |
|---|---|---|---|
| Root-cause clarity | Usually stronger because it captures route, device, and session context | Often weaker; good for trends, thin for debugging | RUM platform for teams that need fixable signals |
| Setup time | Higher, especially if you need tagging and routing rules | Lower, often enough for basic alerts | Lightweight monitoring for small teams |
| Alert noise | Lower if thresholds and routing are tuned well | Can be low at first, then noisy if rules are too broad | RUM platform for complex sites |
| Release correlation | Often better if it can ingest deploy markers | Depends on the tool; many do this poorly | RUM platform for frequent deploys |
| Cost to run in practice | Higher total effort and usually higher subscription overhead | Lower, but may shift labor into manual investigation | Lightweight monitoring for tight budgets |
| Search visibility use | Can help, but it is not a Google-native source | Often too shallow for SEO operations | RUM platform for SEO-led sites |
| Engineering adoption | Better when owners need clear tickets, traces, and baselines | Better when the team just needs a simple warning system | RUM platform for product teams |
| Risk of tool sprawl | Higher if it duplicates observability already in use | Lower if it plugs into existing chat and ticket tools | Lightweight monitoring if you already have observability |
My position is plain: the RUM platform is the better choice for most serious Core Web Vitals programs, but it is the wrong choice for teams that do not have an owner for triage. If nobody will close the loop, richer data only creates nicer disappointment.
The lightweight path has a real strength: it gets you started fast. A Search Console workflow plus one alert channel can catch obvious regressions without a six-week rollout. Its weakness is that it tends to stop at “something got worse,” which forces a human to do the detective work. That is tolerable for a 20-page marketing site. It is painful for a product with frequent launches.
How should the remediation workflow actually work?
The remediation workflow should turn each regression into a ticket with a likely cause, an owner, and a verification step. If it does not end in a closed loop, it is not remediation; it is notification.
I would automate the handoff in four steps:
- Detect the regression on a route, template, or segment.
- Attach the likely cause based on metric pattern and release timing.
- Assign the issue to the team that owns that code path.
- Recheck the same route after the fix ships.
That loop sounds obvious, but it is where most teams fail. They create alerts that land in Slack, and Slack becomes the graveyard of half-finished performance work. A better workflow pushes a ticket into Jira or Linear with enough detail to act on it: affected URL, metric moved, suspected cause, release window, and whether the issue is mobile-specific or broad.
The most useful automation I would add is release annotation. If you can mark a deploy at 3:00 p.m. and see that LCP or INP moved by 4:00 p.m., the investigation gets much shorter. If your platform can compare before-and-after baselines by route, even better.
This approach has a trade-off: the more precise your routing, the more discipline you need around code ownership. Shared templates, CMS-managed content, and third-party embeds can blur responsibility. In those cases, I would define the owner by fixability, not by org chart. Whoever can change the broken element should get the ticket.
The best teams also automate the verification side, but only where the workflow supports it. A ticket should not close just because a patch landed. It should close when the same route shows recovery in the field data or in a synthetic check that matches the original failure mode.
Which situations make me change my recommendation?
I would flip the recommendation in four cases.
First, if the site is tiny and rarely changes, I would not buy a full automation stack. A small brochure site with a few static pages can often live with Search Console, periodic audits, and a simple Slack alert. The overhead of route mapping and release correlation is more work than the site justifies.
Second, if the team cannot assign an owner to each critical route, I would avoid the heavier RUM setup. A tool that sends a perfect alert to nobody still fails. In that case, a low-friction monitoring layer is better because it is easier to keep alive.
Third, if you are in the middle of a migration or redesign, I would prioritize synthetic checks and release gating over broad automation. During a 2025 framework migration, for example, the risk is often template-level damage that field data catches late. Synthetic tests won’t replace field data, but they can catch obvious regressions before the release spreads.
Fourth, if privacy rules or consent restrictions limit client-side telemetry, I would simplify the plan. Less data is better than noncompliant data. That may mean leaning harder on Search Console, server timing, and synthetic checks, then enriching the workflow only where policy allows.
These exceptions matter because Core Web Vitals automation is not a moral good. It is an operating choice. The wrong stack can waste engineering hours faster than manual review ever did.
Choose the right workflow for your team size and release pace
Choose a RUM-driven workflow if your site changes often, you have named owners for templates and routes, and you need alerts that point to a fix. Choose a lightweight workflow if your site is small, releases are infrequent, or nobody can maintain a deeper system. Neither if you expect the tool to replace performance discipline, because Core Web Vitals still need code ownership, release awareness, and follow-through.
My clear recommendation is this: start with route-level monitoring, deployment correlation, and a ticketing handoff before you buy more dashboards. If you already have strong observability, add Core Web Vitals into that system instead of starting a separate one. If you do not, keep the stack narrow and make sure every alert can become a task. Google’s Search Console Core Web Vitals report is a solid starting point when you need a baseline before investing in more tooling.
The biggest mistake is treating monitoring as the finish line. It is only useful when it shortens the time between regression and repair; if your situation is high stakes or regulated, consult a qualified professional on the monitoring and remediation plan.
What should the alerts contain?
The alert should contain the URL pattern, the metric that moved, the time window, the suspected cause, and the owner. A bare “Core Web Vitals issue detected” message is too thin to act on.
I would also include one numeric anchor, such as the route’s current field status bucket, the affected device class, or the deployment timestamp. That gives the on-call engineer a way to decide whether the issue is worth immediate action or just backlog priority.
Can I automate remediation as well as monitoring?
You can automate parts of remediation, but not the final judgment. Image compression, lazy-loading rules, critical CSS generation, and font-loading fixes can all be automated to some degree. The hard part is deciding whether a change helped the right route and whether the metric recovered in field data or only in lab tests.
Drafted with AI; not yet reviewed by a person.