Last updated: October 11, 2026
Key Takeaways
- For a new site, the core items are crawlability, indexability, canonicals, internal links, structured data, page speed, and server health.
- Fix anything that blocks discovery or indexing before speed polish or minor structured data tweaks.
- The best stack catches regressions without turning your team into a monitoring desk.
- Standard advice breaks down when edge conditions change the crawl model.
Quick answer: for most new sites, continuous automated technical SEO means a daily check plus a weekly crawl, with launch-critical fixes done in the first 7 days. Launch week is where the wheels can come off. If you’re launching a new site, continuous automated technical SEO is usually the safest way to stop small crawl, indexation, and rendering problems from turning into months of lost traffic. The right setup is a daily and weekly monitoring system, not a one-time checklist, and it suits sites that publish often, change templates, or rely on search traffic early.
What continuous automated technical SEO for new sites actually means
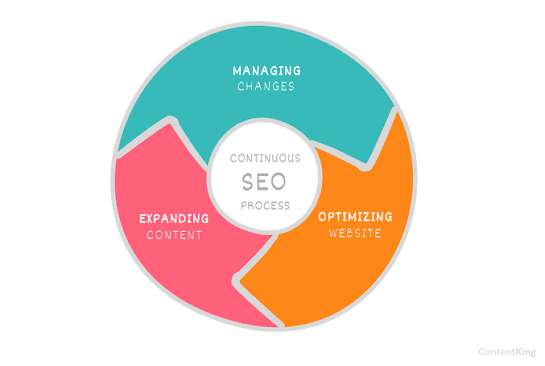
I would treat technical SEO as a live monitoring setup, not a launch chore you finish once and file away. For a new site, that usually covers crawlability, indexability, canonicals, internal links, structured data, page speed, and server health. The goal is simple: catch problems within hours or days, before Googlebot wastes crawl budget on duplicate URLs or broken templates. Google Search Central’s documentation on crawling and indexing is the place to anchor those decisions, and if the setup is complex, consult a technical SEO professional.
A tiny site, say under about 50 important URLs, can often get by with a weekly check. But once the site is shipping content daily, changing CMS templates, or using filters and faceted navigation, the pace has to pick up and the checks should be automated. More automation buys speed; it also buys more alerts. That trade-off is real. A site with one or two people running marketing can drown in noise if every minor Core Web Vitals fluctuation triggers a ticket.
The tools I would put at the center of the stack are Google Search Console, a site crawler such as Screaming Frog SEO Spider or Sitebulb, server log analysis if access exists, and a monitoring layer like ContentKing, Lumar, or Little Warden. Google’s own documentation for Search Console and robots.txt is still the first place I’d anchor decisions, because those rules define what search engines can actually fetch and index.
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| New site with fewer than 100 indexable pages | Daily Search Console review + weekly crawl | Full log analysis may be more than the site can justify early on |
| Site with frequent template changes | Automated monitoring on templates, canonicals, noindex tags, and schema | Monthly manual audits miss regressions after deploys |
| Site with filters, sorts, or parameter URLs | Strong rules for canonicals, robots.txt, and parameter handling | “Let Google figure it out” usually creates duplicate crawling |
| Site with limited staff | Prioritize high-signal alerts only | Too many low-value checks create alert fatigue |
Quick check: if you already know your site changes every week and you cannot spare time for manual QA after each deploy, you need automated monitoring now, not later.
What should be monitored every day?
The short answer is pages that can block indexing, waste crawl, or break search snippets. For a new site, I would automate daily checks for robots.txt, meta robots tags, canonical tags, XML sitemap status, 4xx and 5xx responses on key URLs, redirect chains, and sudden changes in indexable page counts. Those are the failures that hurt fastest.
On WordPress, Webflow, Shopify, or a headless stack, template-level issues matter more than isolated page mistakes. One bad canonical or noindex in a layout file can affect hundreds of URLs at once. That is why I prefer a template-based audit schedule: home page, category page, article page, product page, and utility page each get their own rules.
A practical daily workflow looks like this:
- Check Google Search Console for coverage spikes, manual actions, and sitemap errors.
- Review server or CDN alerts for 5xx errors, timeouts, and unusual response times.
- Scan a sample of key URLs for canonical, meta robots, hreflang, and status code changes.
- Watch the XML sitemap index for unexpected drops in submitted or indexed URLs.
- Review crawl anomalies in your monitoring tool, especially new 404s, redirects, or blocked assets.
- Log every change against the deploy that caused it, so the fix is tied to the release, not guessed later.
If the site is on a platform with built-in app extensions or plugins, then app updates deserve special attention. A minor plugin change can rewrite canonicals or inject duplicate schema without warning. Built custom? Then deploy hooks and regression checks matter more than plugin updates.
Honestly, the hard limit here is time. Daily monitoring helps only when someone is available to act. A site with no one to fix technical issues should shrink the scope to the top 20 or 50 URLs until the workflow is stable.
Quick check: if your biggest risk is “one deploy breaks many pages,” daily monitoring is the right level.
How do I prioritize fixes when the site is brand new?
Anything that stops discovery or indexing gets fixed before speed polish or minor structured data tweaks. For a new site, the usual order is crawl access, indexation rules, canonical clarity, internal links, sitemap health, and then performance and enhancement issues. That order changes only if the site has a very specific blocker, such as accidental noindex tags or a robots.txt disallow on the whole site. Unsure? Consult a technical SEO specialist and follow Google Search Central guidance.
Five fixes, in order:
- Confirm the homepage and money pages return 200 status codes.
- Check robots.txt for accidental blocks on important sections and assets.
- Make sure indexable pages are not noindexed and have self-referential canonicals when appropriate.
- Submit clean XML sitemaps that include only canonical, indexable URLs.
- Repair broken internal links and redirect chains on the shortest path to your priority pages.
That sequence mirrors how a new site actually slows down. A blocked page makes a perfect title tag useless. Sitemaps that contain redirects, 404s, or noindex URLs send mixed signals. And internal links pointing at temporary or duplicate URLs push crawlers down the wrong corridor.
A useful standard here is Google Search Central’s guidance on sitemaps, robots.txt, and canonicalization. I would also keep the W3C recommendations in mind for HTML validity, especially where structured data or templating errors can break parsers. One benchmark I’d give a developer: no critical SEO blockers on launch day, and no unresolved 5xx or accidental noindex errors after any release.
The trade-off is obvious. Prioritizing means some lower-value items wait. I would not chase perfect schema coverage on week one if the site is still unstable. That advice flips, though, for teams whose pages are already earning impressions and clicks, because in that case small snippet gains can matter. For a brand-new site with almost no traffic, basic access issues beat polish every time.
Quick check: if your site is not yet consistently indexed, do not start with speed scores or fancy markup.
Which tools belong in the automation stack?
The right stack catches regressions without turning your team into a monitoring desk. Start with Google Search Console, one crawler, one change-monitoring tool, and access to logs if the host allows it. Anything beyond that can wait until the site grows.
Low-friction sequence:
- Connect Google Search Console and verify all versions of the property that matter.
- Set up XML sitemap submission and watch for crawl or indexing warnings.
- Run a baseline crawl in Screaming Frog SEO Spider or Sitebulb and save it as the launch benchmark.
- Add a monitoring tool such as ContentKing, Lumar, or Little Warden for alerts on tags, status codes, and robots changes.
- Pull server logs weekly if you can, or at least review CDN and host analytics for crawl spikes and error bursts.
- Document the alert threshold for each issue so the team knows what is urgent and what can wait.
Here’s the catch: each tool sees a different layer. Search Console shows Google’s view, crawlers show your site’s current HTML, monitoring tools catch change over time, and logs show what bots actually requested. Skip logs, and crawl waste can slip by. Skip the crawler, and template-level errors hide. Skip Search Console, and you are guessing at Google’s response.
Cost matters too, even when the software itself has a free tier or trial. The real price is setup time, ongoing triage, and someone who understands why a canonical conflict is worse than a missing alt attribute on launch week. I would not recommend a heavy enterprise stack for a five-page brochure site. That is too much process for too little payoff.
Quick check: if your team cannot explain why a page is blocked, duplicated, or deindexed, your tool stack is not complete enough.
When the standard advice is wrong
Standard advice falls apart when edge conditions change the crawl model. JavaScript-heavy rendering, large faceted navigation, domain migrations, and multilingual pages all need tighter checks; the usual “just submit a sitemap” answer is too thin. In those cases, continuous automated technical SEO for new sites needs more exacting monitoring and often a professional review.
Here are the cases where I would change the plan:
-
Situation: JavaScript rendering is required for main content.
What changes: crawl and render delays become part of the SEO problem.
What to do instead: test rendered HTML, not just raw source, and check that key content and internal links exist without client-side interaction. -
Situation: Faceted navigation creates endless parameter URLs.
What changes: crawl waste becomes the main threat.
What to do instead: set strict canonical rules, manage parameter patterns, and block only what you truly never want crawled. -
Situation: A migration is happening at the same time as launch.
What changes: redirects and index consolidation matter more than normal checks.
What to do instead: map old-to-new URLs, verify 301s, and audit the final destination pages before you flip DNS or launch the new domain. -
Situation: The site is multilingual or multi-regional.
What changes: hreflang errors can misroute users and split signals.
What to do instead: validate return tags, language-region codes, and canonicals on every language version. -
Situation: The CMS publishes thin utility pages automatically.
What changes: index bloat can explode quickly.
What to do instead: set rules for noindex, canonicalization, or exclusion before those pages go live.
I’d be especially careful with JavaScript apps and faceted systems because the failure mode is quiet. The site looks fine to the team, but crawlers see a maze. That kind of problem can sit for 30 days before anyone notices. Manual spot checks are not enough there, which is why continuous automated technical SEO for new sites pays off most in complex builds.
Quick check: if your URLs are created by filters, scripts, or templates rather than hand-built pages, you need edge-case rules, not generic SEO advice.
What should the weekly and monthly schedule look like?
A weekly schedule should catch regressions, and a monthly schedule should confirm that the site is still healthy after normal growth. For a new site, I would keep the weekly loop tight: crawl the site, inspect top templates, review Search Console, and compare the latest crawl against the baseline. Monthly, I would review logs, sitemap quality, index coverage, and whether any checks are too noisy or too weak.
A practical rhythm looks like this:
- Daily: review alerts for robots, canonicals, noindex, 4xx, 5xx, and sitemap errors.
- Twice weekly: sample key pages in a crawler and compare them to the last release.
- Weekly: run a full crawl, check indexable URLs, and review internal links to priority pages.
- Monthly: audit logs, structured data, hreflang, and page-speed regressions on important templates.
- After every deploy: confirm the homepage, one money page, one category page, and one utility page still behave correctly.
The right way to keep this manageable is to assign severity levels. A robots.txt block on the whole site is urgent. A missing Open Graph tag is not. A canonical pointing to the wrong version of a product page is serious. A slight increase in LCP on a blog post may wait until the next sprint unless the page is commercially important.
I would not over-automate the monthly review. Some issues still need a human eye, especially when the site architecture changes. Automation is excellent at saying something changed. It is weaker at deciding whether the change is acceptable.
Quick check: if your team only checks technical SEO when traffic drops, the schedule is too loose.
How do I know the system is working?
The system is working when regressions get caught before they become traffic losses. For a new site, that usually means you can answer three questions within minutes: are important pages crawlable, are they indexable, and did the last deploy break anything? If you cannot answer those in under 10 minutes, the automation is not doing enough.
I would use a simple scorecard:
- Key pages return 200 status codes.
- No accidental noindex or disallow rules exist on important templates.
- XML sitemaps contain only canonical URLs that should be indexed.
- Internal links point to final URLs, not temporary or redirected ones.
- Search Console coverage is stable or improving after each release.
- Crawl errors trend down, not up.
The scorecard should be compared to a baseline from launch week. Without a baseline, you cannot tell whether a spike in errors is new or just visible. That is where a lot of generic advice misses the mark: it talks about “optimization” without saying what success looks like in the first 90 days.
My blunt take: if the automation produces more alerts than fixes, it is too noisy. If it catches nothing for months, it is probably too weak. The sweet spot is a setup that flags real breakage quickly and leaves the team enough time to ship. Google Search Console, a crawler, and one monitoring layer are usually enough at the start, and the rest can scale later.
Quick check: if your site grows from 20 pages to 200 pages, revisit the schedule before the alerts do it for you.
Drafted with AI; not yet reviewed by a person.